
Unlocking the Secrets: A Journey Through the World of Machine Learning Algorithms
Machine learning has transformed the way we interact with technology, enabling computers to learn from data and make intelligent decisions without explicit programming. At the heart of this revolution lie machine learning algorithms—mathematical models that uncover patterns, predict outcomes, and automate complex tasks. But what exactly are these algorithms, and how do they work? This journey will explore the fascinating world of machine learning algorithms, from their fundamental principles to their real-world applications.
The Foundation: What Are Machine Learning Algorithms?
Machine learning algorithms are computational procedures designed to improve their performance on a specific task as they are exposed to more data. Unlike traditional programming, where rules are explicitly defined, these algorithms adapt by identifying patterns and relationships within datasets. They can be broadly categorized into three types based on their learning approach:
- Supervised Learning: Algorithms learn from labeled data, where input-output pairs are provided. The model’s goal is to generalize from this data to predict outcomes for new, unseen inputs.
- Unsupervised Learning: These algorithms work with unlabeled data, discovering hidden structures or groupings within the data. Common tasks include clustering and dimensionality reduction.
- Reinforcement Learning: Inspired by behavioral psychology, these algorithms learn by interacting with an environment, receiving rewards or penalties based on their actions. They aim to maximize cumulative reward over time.
Each category serves unique purposes, and the choice of algorithm often depends on the problem at hand, the nature of the data, and the desired outcome.
Diving Deeper: Popular Machine Learning Algorithms Explained
To truly understand machine learning, it’s essential to explore some of the most widely used algorithms across different categories. Below, we break down their mechanisms, strengths, and typical applications.
Supervised Learning Algorithms
Supervised learning is perhaps the most intuitive form of machine learning, mimicking the way humans learn from examples. Some of the most prominent algorithms in this category include:
- Linear Regression: A simple yet powerful algorithm used for predicting continuous numerical values. It models the relationship between a dependent variable and one or more independent variables by fitting a linear equation to the observed data. Ideal for tasks like sales forecasting or real estate price prediction.
- Logistic Regression: Despite its name, logistic regression is used for classification tasks, particularly binary classification (e.g., spam detection or disease diagnosis). It estimates probabilities using the logistic function, allowing for clear yes/no predictions.
- Decision Trees: These algorithms split data into branches based on feature values, creating a tree-like structure of decisions. They are highly interpretable and useful for both classification and regression tasks. Random forests, an ensemble method, build multiple decision trees to improve accuracy and reduce overfitting.
- Support Vector Machines (SVM): SVMs excel in high-dimensional spaces, finding the optimal hyperplane that separates different classes with the maximum margin. They are effective for tasks like image classification and text categorization, especially when data is not linearly separable.
- k-Nearest Neighbors (k-NN): A lazy learning algorithm that classifies new data points based on the majority class of their nearest neighbors in the feature space. It’s simple to implement but can be computationally expensive for large datasets.
Unsupervised Learning Algorithms
Unsupervised learning algorithms uncover patterns in data without prior labels, making them invaluable for exploratory data analysis and anomaly detection. Key algorithms in this category include:
- k-Means Clustering: Groups data points into k clusters based on their similarity, minimizing the variance within each cluster. Widely used in customer segmentation, image compression, and anomaly detection.
- Principal Component Analysis (PCA): A dimensionality reduction technique that transforms high-dimensional data into a lower-dimensional space while preserving most of the variance. Useful for visualizing complex datasets and improving computational efficiency.
- Apriori Algorithm: Identifies frequent itemsets and association rules in transactional datasets, commonly used in market basket analysis to discover products frequently purchased together.
- Autoencoders: Neural network-based algorithms that learn efficient representations of data by compressing it into a latent space and then reconstructing it. They are often used for anomaly detection and feature extraction.
Reinforcement Learning Algorithms
Reinforcement learning (RL) algorithms learn by trial and error, optimizing decisions to achieve long-term rewards. This approach is particularly useful in dynamic environments where traditional supervised learning falls short. Notable algorithms include:
- Q-Learning: A model-free RL algorithm that learns the value of actions in a given state by updating a Q-table. It’s used in robotics, game AI (e.g., AlphaGo), and autonomous driving to make sequential decisions.
- Deep Q-Networks (DQN): Combines Q-learning with deep neural networks to handle high-dimensional state spaces, such as those found in video games and complex control systems. DQN has achieved human-level performance in many Atari games.
- Proximal Policy Optimization (PPO): A policy gradient method that balances exploration and exploitation by updating policies in a way that avoids drastic changes. PPO is widely used in robotics, finance, and natural language processing for optimizing sequential decisions.
- Monte Carlo Tree Search (MCTS): A heuristic search algorithm that combines tree search with random sampling to make decisions in large state spaces. It’s the backbone of AI systems like AlphaGo and chess engines.
The Inner Workings: How Machine Learning Algorithms Learn
At their core, most machine learning algorithms operate by iteratively adjusting parameters to minimize an error function, often referred to as the “loss function.” This process, known as optimization, is typically driven by techniques like gradient descent. Here’s a step-by-step breakdown of how learning occurs:
- Data Collection and Preprocessing: The first step involves gathering relevant data and preparing it for training. This may include cleaning missing values, normalizing features, and encoding categorical variables.
- Model Selection: Choose an appropriate algorithm based on the problem type (classification, regression, clustering, etc.) and the data’s characteristics.
- Training: The model is exposed to training data, and its parameters are adjusted to minimize the loss function. For example, in linear regression, the algorithm tweaks the slope and intercept to fit the data points as closely as possible.
- Evaluation: The model’s performance is assessed using a separate validation dataset to ensure it generalizes well to unseen data. Metrics like accuracy, precision, recall, or mean squared error are used depending on the task.
- Hyperparameter Tuning: Fine-tuning parameters (e.g., learning rate, tree depth, or number of clusters) to optimize the model’s performance. Techniques like grid search or Bayesian optimization are often employed here.
- Deployment and Monitoring: Once trained and validated, the model is deployed in real-world applications. Continuous monitoring ensures it performs as expected and adapts to new data over time.
Choosing the Right Algorithm: A Practical Guide
With hundreds of machine learning algorithms available, selecting the right one can be daunting. The choice depends on several factors, including the problem type, data size, computational resources, and interpretability requirements. Here’s a practical guide to help navigate this decision:
Consider the Problem Type
Align the algorithm with the nature of the problem:
- Classification: Use algorithms like logistic regression, decision trees, or SVMs for tasks such as spam detection or image recognition.
- Regression: Opt for linear regression, polynomial regression, or neural networks when predicting continuous values like stock prices or temperature.
- Clustering: Apply k-means, hierarchical clustering, or DBSCAN for grouping similar data points, such as customer segmentation.
- Dimensionality Reduction: Use PCA, t-SNE, or autoencoders to reduce the number of features while preserving essential information.
- Reinforcement Learning: Employ Q-learning, DQN, or PPO for problems requiring sequential decision-making, such as robotics or game AI.
Evaluate Data Characteristics
The quality and structure of the data play a crucial role in algorithm selection:
- Data Size: For small datasets, simpler algorithms like linear regression or k-NN may suffice. For large datasets, consider scalable models like deep learning or ensemble methods.
- Data Type: Categorical data may require algorithms like decision trees or Naive Bayes, while numerical data can leverage linear models or neural networks.
- Data Distribution: If data is highly skewed or contains outliers, robust algorithms like random forests or support vector machines may perform better.
- Missing Values: Algorithms like k-NN or decision trees can handle missing data better than linear models or SVMs.
Balance Performance and Interpretability
While some algorithms (e.g., deep neural networks) offer high accuracy, they often come at the cost of interpretability. Others, like decision trees or linear regression, provide clear insights into how decisions are made. Consider the trade-off based on the application:
- Interpretable Models: Use linear models, decision trees, or rule-based systems for applications where transparency is critical, such as healthcare diagnostics or financial audits.
- Black-Box Models: For complex tasks like natural language processing or image recognition, deep learning models (e.g., convolutional neural networks) may be necessary, even if they lack interpretability.
Leverage Ensemble Methods
Ensemble methods combine multiple algorithms to improve performance and robustness. Popular techniques include:
- Bagging (e.g., Random Forest): Reduces variance by training multiple models on different subsets of data and averaging their predictions.
- Boosting (e.g., XGBoost, AdaBoost): Sequentially trains models, each correcting the errors of the previous one, to improve accuracy.
- Stacking: Uses a meta-model to combine predictions from multiple base models, often leading to superior performance.
Real-World Applications: Where Machine Learning Algorithms Shine
Machine learning algorithms are not just theoretical constructs—they power some of the most transformative technologies across industries. Here are a few compelling examples of their real-world applications:
Healthcare
- Disease Diagnosis: Algorithms like convolutional neural networks (CNNs) analyze medical images (e.g., X-rays, MRIs) to detect tumors, fractures, or other abnormalities with high accuracy.
- Drug Discovery: Machine learning models predict how different compounds will interact with biological targets, accelerating the development of new drugs.
- Personalized Treatment: Recommender systems analyze patient data to suggest tailored treatment plans, improving outcomes and reducing side effects.
- Predictive Analytics: Hospitals use algorithms to predict patient readmission rates, optimize staffing, and allocate resources efficiently.
Finance
- Fraud Detection: Anomaly detection algorithms identify unusual transactions by analyzing patterns in spending behavior, reducing financial losses.
- Algorithmic Trading: Reinforcement learning and time-series forecasting models execute trades at optimal times, maximizing profits while minimizing risk.
- Credit Scoring: Supervised learning models evaluate the creditworthiness of loan applicants by analyzing historical data and financial indicators.
- Customer Segmentation: Unsupervised learning clusters customers based on behavior, enabling targeted marketing and personalized offers.
Retail and E-Commerce
- Recommendation Systems: Collaborative filtering and deep learning models suggest products to users based on their browsing and purchase history, driving sales and engagement.
- Dynamic Pricing: Algorithms adjust prices in real-time based on demand, competition, and other factors, optimizing revenue and competitiveness.
- Inventory Management: Predictive models forecast demand for products, helping retailers maintain optimal stock levels and reduce waste.
- Chatbots and Virtual Assistants: Natural language processing (NLP) models power chatbots that handle customer inquiries, improving service efficiency and user experience.
Autonomous Systems
- Self-Driving Cars: Reinforcement learning and computer vision algorithms enable vehicles to perceive their environment, make decisions, and navigate safely.
- Robotics: Motion planning algorithms allow robots to perform tasks in dynamic environments, from warehouse automation to surgical assistance.
- Drone Navigation: Algorithms process sensor data to control drone flight paths, enabling applications like aerial photography, agriculture, and search-and-rescue missions.
Entertainment and Media
- Content Recommendation: Streaming platforms like Netflix and Spotify use collaborative filtering and deep learning to recommend movies, shows, and music tailored to user preferences.
- Content Generation: Generative adversarial networks (GANs) and transformers create realistic images, videos, and text, powering applications like deepfake detection and AI-generated art.
- Sentiment Analysis: NLP models analyze social media posts, reviews, and comments to gauge public opinion and brand perception.
Challenges and Ethical Considerations in Machine Learning
While machine learning algorithms offer immense potential, they also present significant challenges and ethical dilemmas. Addressing these issues is crucial for responsible and sustainable AI development.
Data Bias and Fairness
Machine learning models are only as good as the data they are trained on. Biased or unrepresentative data can lead to unfair outcomes, reinforcing societal inequalities. For example:
- Algorithmic Bias: Models trained on biased historical data may perpetuate discrimination in hiring, lending, or law enforcement.
- Demographic Skew: If training data lacks diversity, models may perform poorly for underrepresented groups, leading to disparate impacts.
Mitigation strategies include:
- Using diverse and representative datasets.
- Implementing fairness-aware algorithms (e.g., adversarial debiasing).
- Regularly auditing models for bias and discrimination.
Overfitting and Generalization
Overfitting occurs when a model learns the training data too well, including its noise and outliers, resulting in poor performance on unseen data. This is a common challenge in machine learning, particularly with complex models like deep neural networks.
Techniques to combat overfitting include:
- Regularization: Adding penalty terms (e.g., L1 or L2 regularization) to the loss function to discourage overly complex models.
- Cross-Validation: Splitting data into multiple subsets to evaluate model performance robustly.
- Early Stopping: Halting training when validation performance starts to degrade.
- Dropout: Randomly deactivating neurons during training in neural networks to prevent co-adaptation.
Interpretability and Explainability
Many advanced machine learning models, such as deep neural networks, operate as “black boxes,” making it difficult to understand how they arrive at decisions. This lack of transparency can be problematic in high-stakes applications like healthcare or finance.
Approaches to improve interpretability include:
- Model-Specific Methods: Using inherently interpretable models like decision trees or linear models where possible.
- Post-Hoc Explanation: Techniques like SHAP (SHapley Additive exPlanations) or LIME (Local Interpretable Model-agnostic Explanations) to explain individual predictions.
- Visualization: Creating tools to visualize model decision paths or feature importance.
Privacy and Security
Machine learning often relies on vast amounts of personal data, raising concerns about privacy and security. Issues include:
- Data Leakage: Accidentally including sensitive information in training data, leading to privacy breaches.
- Adversarial Attacks: Malicious actors manipulating input data to deceive models (e.g., fooling image recognition systems with adversarial examples).
- Federated Learning: A decentralized approach where models are trained on local devices without sharing raw data, preserving user privacy.
Solutions to enhance security include:
- Implementing differential privacy to add noise to data while preserving utility.
- Using homomorphic encryption to perform computations on encrypted data.
- Adopting robust validation techniques to detect adversarial examples.
Computational Resources and Sustainability
Training complex machine learning models, especially deep neural networks, requires significant computational power, leading to high energy consumption and environmental impact. For instance, training a single large language model can emit as much carbon as five cars in their lifetimes.
Efforts to promote sustainability in machine learning include:
- Efficient Models: Developing lightweight models (e.g., TinyML) that can run on edge devices with minimal resources.
- Green AI: Optimizing algorithms and hardware to reduce energy consumption during training and inference.
- Model Compression: Techniques like pruning, quantization, and distillation to shrink model size without sacrificing performance.
The Future of Machine Learning Algorithms
As technology advances, machine learning algorithms continue to evolve, unlocking new possibilities and addressing emerging challenges. Here’s a glimpse into the future of this dynamic field:
Advancements in Deep Learning
Deep learning, a subset of machine learning powered by neural networks, is driving breakthroughs in AI. Future trends include:
- Transformers and Self-Attention: Models like BERT and GPT leverage self-attention mechanisms to process sequential data more effectively, enabling advancements in NLP and computer vision.
- Neural Architecture Search (NAS): Automated methods to design optimal neural network architectures, reducing the need for manual tuning.
- Foundation Models: Large-scale models pre-trained on vast datasets that can be fine-tuned for a wide range of tasks, democratizing access to advanced AI capabilities.
Explainable and Responsible AI
The demand for transparent and ethical AI is growing, leading to innovations in:
- Causal AI: Algorithms that not only predict but also explain causal relationships in data, enabling more robust and interpretable decision-making.
- Fairness-Aware Learning: Techniques to ensure models are equitable and do not perpetuate biases.
- AI Governance: Frameworks and regulations to ensure responsible AI development and deployment, such as the EU’s AI Act.
Edge AI and TinyML
As the Internet of Things (IoT) expands, there’s a growing need to deploy machine learning models on edge devices (e.g., smartphones, sensors, wearables) with limited computational power. TinyML, a field focused on lightweight models, is making this possible by enabling:
- Real-Time Processing: Models that run locally on devices, reducing latency and dependency on cloud services.
- Privacy Preservation: Processing sensitive data on-device rather than sending it to the cloud.
- Energy Efficiency: Models optimized for low-power consumption, extending battery life in portable devices.
Quantum Machine Learning
Quantum computing holds the potential to revolutionize machine learning by solving complex problems exponentially faster than classical computers. Quantum machine learning (QML) explores algorithms that leverage quantum mechanics, such as:
- Quantum Neural Networks: Neural networks that operate on quantum bits (qubits), enabling faster training and inference.
- Quantum Kernels: Quantum-enhanced versions of classical kernels used in SVMs for classification tasks.
- Hybrid Models: Combining classical and quantum computing to tackle problems like optimization and cryptography.
While still in its infancy, quantum machine learning could unlock new frontiers in AI, particularly in fields like drug discovery, finance, and materials science.
Getting Started with Machine Learning Algorithms
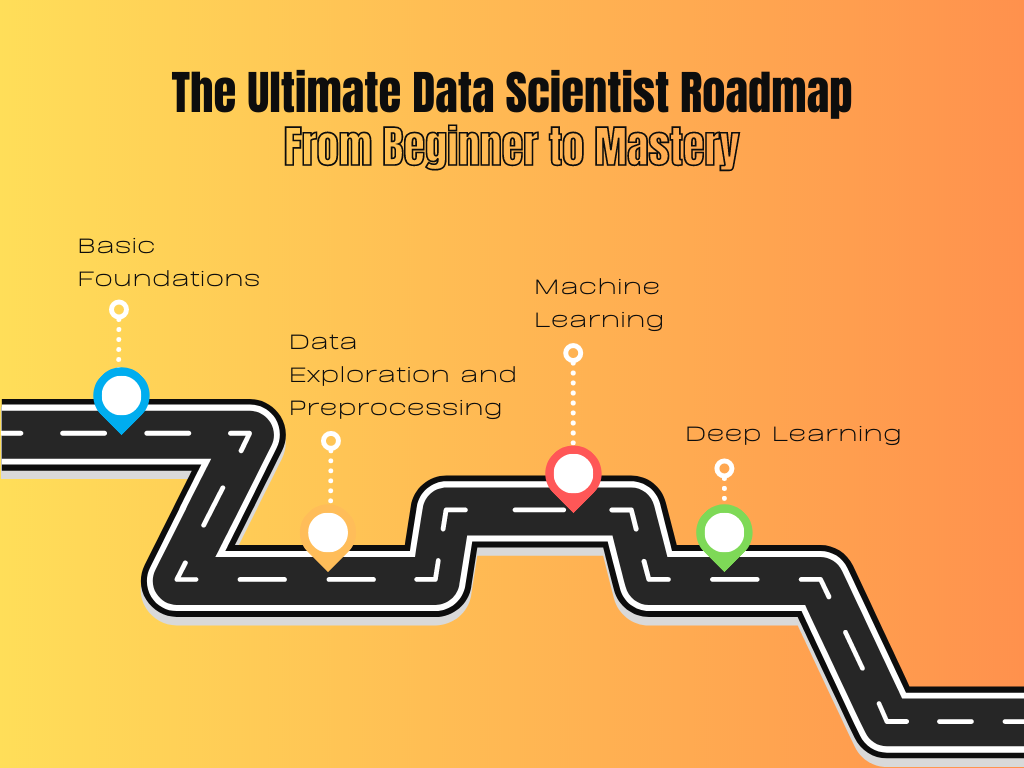
Embarking on a journey into machine learning can be both exciting and overwhelming. Whether you’re a beginner or an experienced practitioner looking to expand your skills, here are some steps to help you get started:
Learn the Fundamentals
Build a strong foundation in mathematics and computer science:
- Mathematics: Focus on linear algebra, calculus, probability, and statistics. These are essential for understanding how machine learning algorithms work.
- Programming: Learn Python, the most popular language for machine learning, along with libraries like NumPy, Pandas, and Scikit-learn. For deep learning, familiarize yourself with frameworks like TensorFlow and PyTorch.
- Theory: Study the core concepts of machine learning, including supervised vs. unsupervised learning, bias-variance tradeoff, overfitting, and regularization.
Hands-On Practice
The best way to learn is by doing. Start with beginner-friendly projects and gradually tackle more complex challenges:
- Kaggle: Participate in competitions and explore datasets on Kaggle, a platform for data science and machine learning.
- Open-Source Projects: Contribute to open-source machine learning projects on GitHub to gain practical experience and collaborate with others.
- Personal Projects: Build your own models to solve real-world problems, such as predicting stock prices, classifying images, or analyzing sentiment in text.
Take Online Courses and Tutorials
There are numerous resources available to deepen your understanding of machine learning algorithms:
- Coursera: Courses like “Machine Learning” by Andrew Ng or “Deep Learning Specialization” by deeplearning.ai.
- edX: Programs from top universities, such as “Introduction to Artificial Intelligence” by Columbia University.
- Fast.ai: Practical deep learning courses focused on real-world applications.
- YouTube: Channels like 3Blue1Brown, StatQuest with Josh Starmer, and sentdex offer excellent tutorials on machine learning concepts.
Join the Community
Engage with the machine learning community to stay updated, share knowledge, and seek guidance:
- Forums: Participate in discussions on Reddit (e.g., r/MachineLearning), Stack Overflow, or specialized forums like Data Science Stack Exchange.
- Meetups and Conferences: Attend local meetups, webinars, or conferences like NeurIPS, ICML, or CVPR to network with professionals and learn about the latest advancements.
- Blogs and Newsletters: Follow blogs like Towards Data Science, Distill.pub, or newsletters like The Batch by DeepLearning.AI to stay informed about trends and research.
Experiment and Innovate
Machine learning is a field that thrives on experimentation. Don’t be afraid to try new algorithms, tweak parameters, or combine techniques to see what works best for your problem. Some tips for innovation include:
- Replicate Research Papers: Implement algorithms described in cutting-edge research papers to understand their practical applications.
- Participate in Hackathons: Join hackathons focused on AI and machine learning to collaborate with others and solve challenging problems under time constraints.
- Explore Emerging Trends: Keep an eye on emerging areas like federated learning, self-supervised learning, or neuromorphic computing to stay ahead of the curve.
Conclusion: The Path Forward in Machine Learning
Machine learning algorithms are the driving force behind some of the most transformative technologies of our time. From personalized recommendations to autonomous vehicles, these algorithms are reshaping industries and improving lives. However, their potential is matched by their complexity and the challenges they present, from ethical concerns to computational limitations.
As we look to the future, the field of machine learning will continue to evolve, driven by advances in deep learning, quantum computing, and responsible AI. For aspiring practitioners, the journey begins with a solid understanding of the fundamentals, hands-on practice, and a commitment to lifelong learning. For seasoned professionals, the opportunities lie in pushing the boundaries of what’s possible, addressing real-world problems, and ensuring that AI is developed and deployed ethically and sustainably.
The world of machine learning is vast and ever-changing, but one thing is certain: the algorithms we build today will shape the technologies of tomorrow. By unlocking their secrets, we not only harness their power but also pave the way for a smarter, more connected, and more innovative future.